You know AI is improving your campaigns when a controlled comparison says so. Hold back a randomly chosen group that does not get the AI-driven change, run both side by side, and compare the business result, not just the platform's own report. If the exposed group does not beat the holdout by more than normal noise, the improvement is not proven.
Key takeaways
- Platform dashboards report results that happened, not results the ads caused.
- A holdout group, where a random slice never sees the change, is the simplest honest test.
- Test the AI change itself — creative, bidding or targeting — one at a time.
- Set guardrail metrics so a gain in one number does not hide a loss in another.
- Decide the success measure, the budget and the stopping rule before the test starts.
Why can't you trust the dashboard?
Because the dashboard counts conversions that would often have happened anyway. Automated bidding is good at finding people who were already likely to buy, and that makes results look strong without adding sales.
Three things inflate before-and-after comparisons. Seasonality moves demand on its own. Budgets and offers change at the same time as the AI feature. And an algorithm that targets likely buyers is credited with sales it did not create. A comparison that does not control for these tells you what happened, not why.
What is a holdout group?
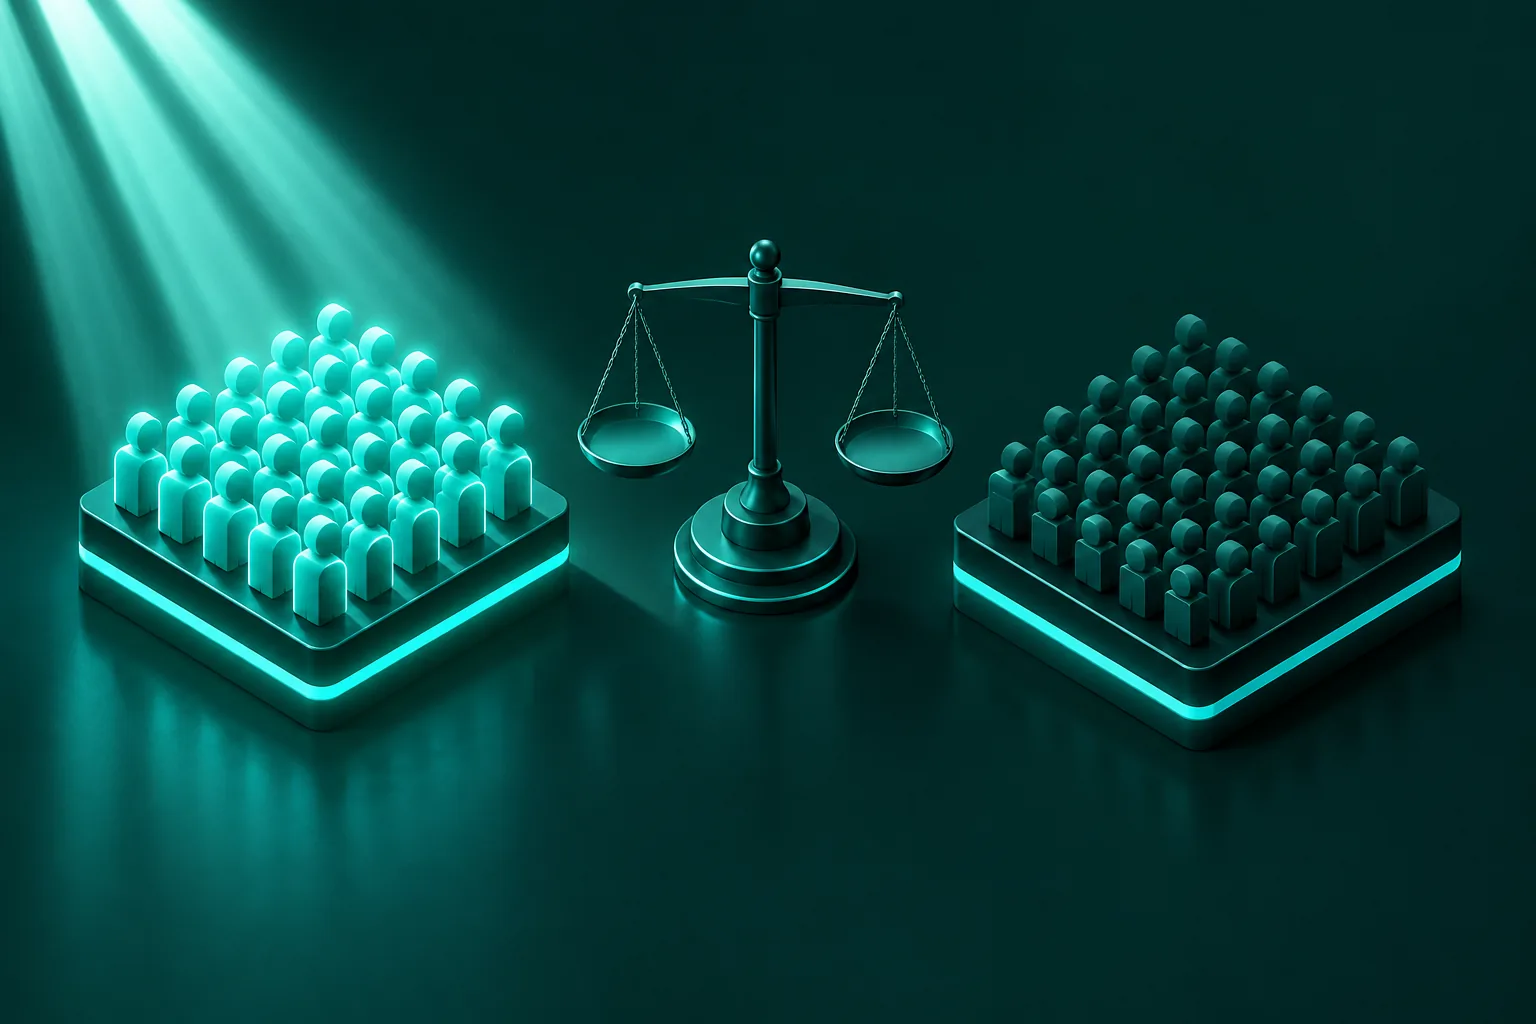
A holdout is a randomly selected group of people, or places, that does not receive the ads or the change you are testing. Its results show what would have happened without it.
Google describes its Conversion Lift tool in these terms: it splits an audience into a treatment group that sees the ads and a control group that does not, and the difference in conversions between them is the lift. Studies can be split by users or by geography, and Google notes the tool is not available for all accounts. Meta offers lift studies built on the same idea; check its current documentation and your account's access.
If you cannot run a platform study, a manual version works for many accounts: pause the activity in a few matched regions, keep it live in others, and compare.
What is incrementality?
Incrementality is the extra result caused by marketing, over and above what would have happened anyway. It is the number a holdout test estimates.
A hypothetical example: a retailer sees 1,000 sales a month in a region where ads run and 800 in a matched region where they are paused. The incremental effect is about 200 sales, not 1,000. Divide the spend by 200 to get the true cost per extra sale. That cost is usually higher than the dashboard's.
How do you test the AI change itself?
Change one thing at a time and give each test a clear comparison. Three tests cover most uses of AI in campaigns.
| AI change | Test design | Primary measure |
|---|---|---|
| AI-written or AI-generated creative | A/B test against your current best ad, same audience, same budget, same period | Cost per result, or conversion rate |
| Automated bidding or budget tools | Split by region or by audience, or use the platform's experiment feature | Incremental conversions per unit of spend |
| New audience targeting | Holdout of the expanded audience | Incremental sales, new-customer share |
Before you spend, you can cut weak creatives with pre-scoring, as in our guide to predicting ad performance. That narrows the field. The live test still decides.
What are guardrail metrics?
Guardrail metrics are numbers that must not get worse while you chase the main goal. They stop a "win" that quietly damages something else.
- Cost and margin: cost per acquisition, return on spend after discounts.
- Customer quality: returns, refunds, repeat purchase and lead-to-sale rate.
- Brand safety and tone: complaints, hides, negative comments, off-brand outputs.
- Creative variety: if the AI converges on one look, fatigue arrives sooner.
How do you run the test properly?
- Write the question. "Does the AI version beat our current approach on cost per qualified lead?"
- Fix the measure, budget and duration before launch, and do not change them mid-test.
- Randomise. Assign groups by chance, not by judgement.
- Run long enough to cover your normal buying cycle and to leave the platform's learning phase.
- Check size. Tiny groups give noisy answers; if results swing wildly day to day, treat the outcome as unproven.
- Record the result, including tests where AI made no difference. A no-difference result still saves money.
What if the test shows no improvement?
Treat that as a useful answer. AI may have saved time without changing results, which can still be worth it, as long as you say so. Our piece on why more AI content is not making campaigns better explains one common reason: more output is not the same as better output.
FAQ
What is the difference between A/B testing and incrementality testing?
An A/B test compares two versions of something, such as two ads, both shown to people. An incrementality test compares showing against not showing. Use A/B tests to pick a better creative, and holdouts to find out whether the spend adds sales at all.
How big should a holdout be?
As small as gives a readable answer, because every held-back person is a missed sale. The right size depends on your volume and the effect you expect to detect. Ask your analyst or the platform's study tool to estimate it.
How long should a lift test run?
Long enough to cover your usual buying cycle and any learning period. A few days is rarely enough for considered purchases. Set the duration before you start.
Can I measure AI impact without a holdout?
You can estimate it with before-and-after or matched-market comparisons, but these are weaker. Label them as estimates, and confirm important decisions with a proper control when you can.
Do I need to test every AI feature?
No. Test the changes that carry real budget or risk first. Small, reversible tweaks can be monitored with guardrail metrics instead.
Sources
- Google Ads Help, About Conversion Lift.
- SOMIN posts: Predict ad performance before you spend and Why more AI content is not making campaigns better.